yousan
Japanese turn-detection models (Easy Turn / FastTurn)
Japanese versions of Easy Turn and FastTurn, turn-detection models that judge speech endings in four states.
Overview
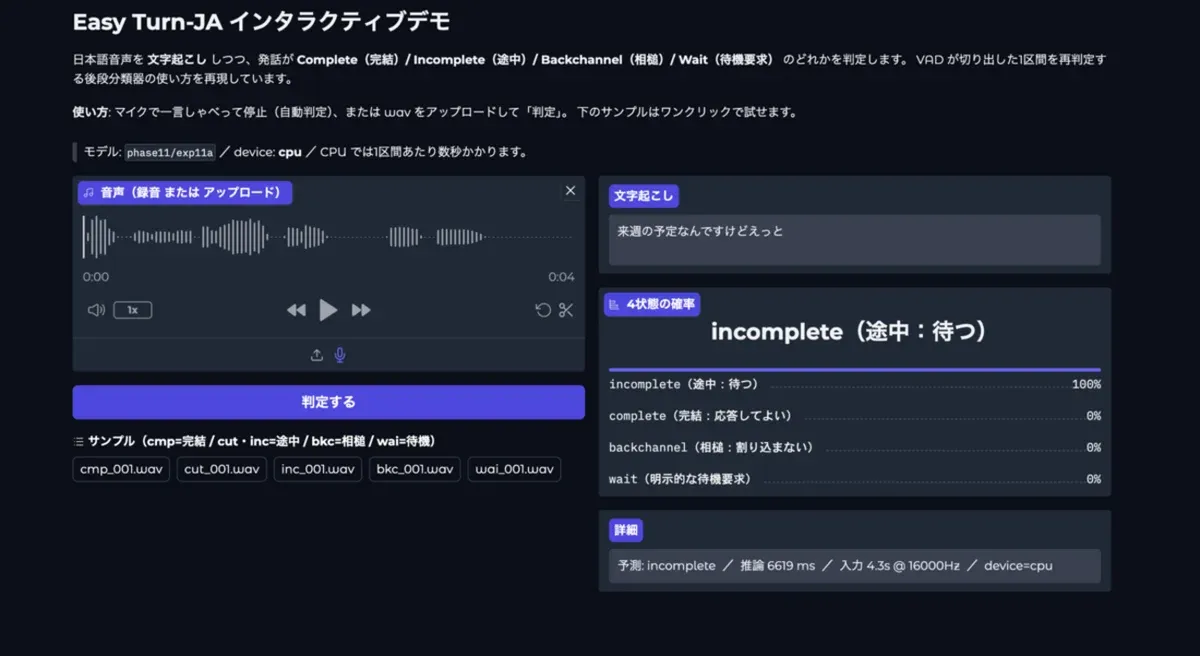
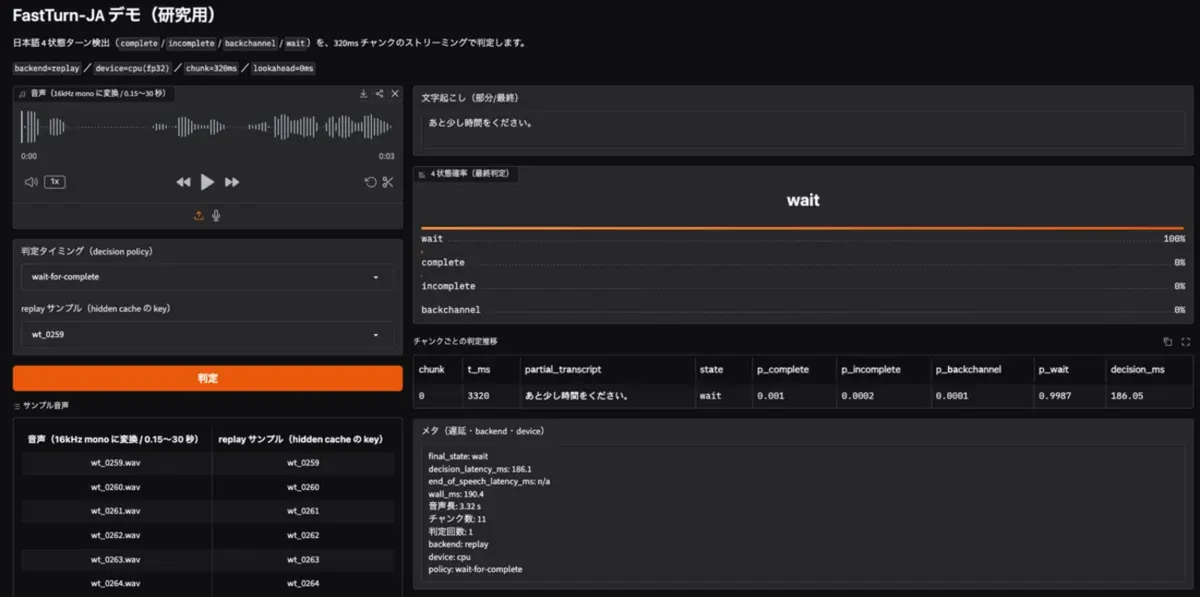
I built two Japanese turn-detection models that decide whether a speaker has finished talking in a voice dialogue. Both classify speech into four states: Complete, Incomplete, Backchannel and Wait. The Easy Turn Japanese model combines a Whisper-Medium encoder, an adapter and Qwen2.5-0.5B-Instruct. The FastTurn Japanese model combines the nemotron-3.5-asr-streaming-0.6b encoder with Qwen3-0.6B.
What I did
I prepared the training data (ReazonSpeech, J-CHAT, TalkBank and synthetic data generated with Irodori-TTS), trained and evaluated the models, and published them.
Technical notes
The write-ups record a P50 latency of 111.6 ms on an RTX 4090 for the Easy Turn model and a P95 of 110.2 ms (encoder plus detector) for the FastTurn model. The Easy Turn Japanese model is licensed CC BY-NC-SA 4.0.